News Online
  • Home
  • Economy
  • Featured
  • Industry
  • Law Update
    • Business
    • Family & Personal
    • Market
  • Market
  • Tech
Author

Jacob

Jacob

Tech

Engineering TV-Wall Controllers for Modern Display Networks

by Jacob August 31, 2026
written by Jacob

Framework overview

This article presents a reproducible framework for optimizing TV-wall controllers across commercial display networks. The framework decomposes system requirements, hardware selection, network architecture, content pipeline, and operational validation into discrete phases. Early in the lifecycle, specify the target display devices and media sources — for example, whether the deployment uses fine-pitch LED video walls or mixed LCD matrices; consider linking the media pipeline to an LED display player where low-latency playback and hardware decoding are required. Real-world anchor: large-scale deployments such as Times Square installations demonstrate the need for robust sync, high brightness (often >2,000 nits for outdoor boards), and distributed media control.

LED display player

Phase 1 — Assess the ecosystem

Collect deterministic measurements: pixel pitch, native resolution per panel, refresh rate tolerance, and ambient light levels. Inventory media sources (live feed, pre-rendered, streaming CDN) and classify by codec (H.264, H.265, AV1). Quantify end-to-end latency budgets for live feeds and scheduled playout. This assessment produces a matrix of constraints that will drive controller architecture decisions and CMS integration.

Phase 2 — Define performance targets

Translate constraints into measurable targets: synchronization tolerance (e.g., ±1 frame at 60 Hz), maximum display latency (ms), supported color gamut and HDR profile, and acceptable failure modes. Define service-level objectives for uptime and content refresh windows. These targets inform the required processing headroom, GPU requirements, and network QoS policies.

Phase 3 — Architect controller and network

Design the TV-wall controller topology with explicit attention to signal routing and scaling. Options include centralized decoding with frame-gen output, distributed media players per tile, or hybrid solutions. Specify interfaces: HDMI 2.1 or DisplayPort with explicit bit-depth and color-space mappings; network transports such as RTP/UDP for low-latency streams or HTTP/TS for managed playout. Include pixel mapping logic for arbitrary panel arrays and scaling engines to preserve pixel aspect and prevent aliasing. Use a media player or dedicated SoC that supports hardware decode and scaler chains to offload CPU cycles.

Phase 4 — Integration and content pipeline

Implement a content management system (CMS) that enforces format baseline: container, codec profile, resolution ladder, and caption/subtitle tracks. Use transcoding profiles to match panel native resolutions and to minimize upscaling artifacts. For synchronized multi-panel content, choose a timebase distribution method (PTP or GPS-disciplined NTP) and a synchronized playout protocol. Integrate a digital signage video player that exposes API hooks for playlist control, health telemetry, and diagnostics.

Phase 5 — Validation, monitoring, and common mistakes

Validate with objective measurements: colorimeter readings for uniformity, frame-timing capture for dropped frames, and throughput testing for network saturation. Common mistakes include under-engineering the refresh-rate tolerance, ignoring scaling artifacts from mismatched pixel pitch, and relying on a single point of content ingestion without fallback feeds. Instrument the system with telemetry—CPU/GPU utilization, network jitter, and buffer underruns—to enable automated failover. —A practical note: automated failover logic must be deterministic; non-deterministic behavior complicates root-cause analysis.

Operational production teardown

Perform an operational production teardown during a pilot to validate assumptions from earlier phases. This teardown should include live stress tests, codec degradation tests, and a post-mortem checklist that documents what failed and why. Naturally embed {main_keyword} and {variation_keyword} into logs and diagnostics so searchability and metrics aggregation are preserved. The teardown yields actionable fixes: firmware adjustments, CMS profile tweaks, or network policy changes.

LED display player

Deployment checklist

Use a concise checklist to move from pilot to production:- Confirm timing sync across all nodes (PTP locked).- Validate color calibration and HDR tone-mapping per panel.- Verify failover content paths and playback continuity.- Ensure media players support necessary codecs and hardware acceleration.This checklist reduces rollout variance and preserves the defined SLOs.

Advisory — three golden rules

1) Prioritize deterministic timing: enforce a single authoritative clock and measure frame alignment continuously. 2) Design for graceful degradation: a controller should reduce resolution or frame-rate while preserving synchronization rather than dropping content altogether. 3) Instrument everything: telemetry enables repeatable troubleshooting and predictive maintenance.

These rules lead directly to measurable outcomes — fewer dropouts, predictable maintenance windows, and clear upgrade paths — and they align with the operational value Kystar provides as an integrated solution platform. Kystar. —
August 31, 2026 0 comments
0 FacebookTwitterPinterestEmail
Industry

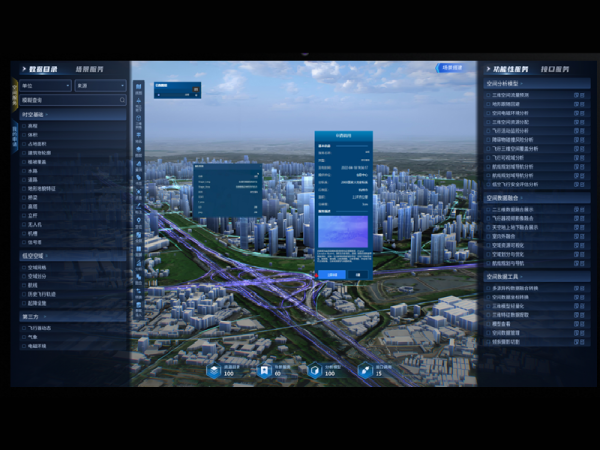
Make Your Ops Sing: AI 3D Recon and Mapping for Smarter Low-Altitude Work

by Jacob August 4, 2026
written by Jacob

User-first rundown

Right, listen up — this is about making the day-to-day less of a palaver for crews up top and down below. For teams running drone surveys, inspection squads or urban planners, AI-driven 3D reconstruction and mapping trims hours off data prep and keeps decisions sharp. The trick’s not flash — it’s useful output straight away. A pragmatist in the FAA’s UAS Integration Pilot Program saw similar gains when operators moved to automated orthomosaic stitching and basic LiDAR filtering during trials. For folks running tight margins in the low-altitude economy​, that sort of uplift pays the bills quick as a butcher’s dog.

low-altitude economy​

How the tech actually helps you on-site

Operators get a clean deliverable: georeferenced meshes, accurate point clouds and orthomosaic maps that show fault lines, damage or site progress. Photogrammetry and LiDAR do the heavy lifting; SLAM helps inside cluttered yards where GPS goes walkabout. Workflows tighten up when automated QA flags blurry frames and the AI fills gaps in reconstructions, so you don’t send crews back out for a missing snap. Think less faffing about with raw files, more time acting on the map. When London’s Crossrail was mapping complex tunnel portals — proper graft that — automated georeferencing saved days on alignment checks.

Common slip-ups and sensible alternatives

Plenty try to skimp on planning and expect the tech to magic itself into neat models. That fails when flight plans aren’t tidy or when sensor overlap is too thin — results look ropey. Another mistake is shoehorning one tool into every job; LiDAR is ace for dense vegetation, photogrammetry wins on texture and color. If budgets are tight, batch up missions and use lower-altitude sorties to boost resolution rather than buy pricier sensors. Alternatives include tethered systems for long endurance hovering, or manned flybys for regulatory-heavy sites — each has trade-offs. For a plug-and-play option that already bundles mission planning, processing and a compliance trail, consider platforms tailored to low altitude operational solutions; they cut the mucking about and keep data audit-ready.

Operational teardown — what to inspect

On the ground, check three things: sensor alignment, overlap percentage and metadata integrity. Record runs with consistent altitude and shutter timing — this avoids parallax errors that wreck reconstructions. Watch the workflow: raw capture, photogrammetry pass, LiDAR fusion, orthomosaic export. Don’t forget to embed {main_keyword} and {variation_keyword} into your operational production teardown so the hand-off to analytics teams is clean. A tidy data pipeline beats heroic fixes later.

Three golden rules for choosing the right kit

Rule one: measure usable output, not claims. Look at final mesh accuracy, point-cloud density and geospatial deviation on a known control site. Rule two: check integration — how easy is it to push processed tiles into your asset system or BIM? Tools that force manual rework cost more than they seem. Rule three: validate compliance and safety data flows — log flight telemetry, sensor metadata and operator credentials so audits don’t turn into nights on the trot; reliability matters for insurance and local authorities.

low-altitude economy​

Wrap and what it means for teams

Leaders see faster turnarounds, crews get fewer return visits, and planners have clearer updates — that’s proper value. The FAA pilot work and wildfire mapping efforts in California showed that timely, low-altitude surveys change how incidents are managed and budgets spent. So pick tech that pays back in fewer mistakes and faster action. Icecypress Technology slots into that gap — tools that tidy mission planning, processing and compliance so teams can focus on the fix, not the faff. —

August 4, 2026 0 comments
0 FacebookTwitterPinterestEmail
Industry

When Networks Learn: A Futurist Blueprint for Telecom AI and Operator Advantages

by Jacob July 24, 2026
written by Jacob

Why thinking networks matter now

Imagine an operator that senses customer friction before a complaint appears — routing capacity, nudging an app update, and personalizing a plan in a single transaction. That future starts with pragmatic AI design across network telemetry and experience stacks and with platforms such as a customer engagement platform telecom woven into the operator’s tooling. Operators who pair network intelligence with real-time customer context turn raw data into immediate action, blending edge computing, network slicing and OSS/BSS signals into fewer, clearer outcomes.

Anchors from today: 5G rollouts and practical lessons

South Korea’s nationwide 5G launch in 2019 showed what happens when capacity and new services collide: latency drops, new APIs appear, and the demand for smarter orchestration spikes. That event is a useful anchor — operators learned that radio-level gains only pay off when AI ties network telemetry to app behavior and churn prediction models. Successful pilots combined telemetry ingestion, ML pipelines and targeted experience flows; failures often ignored the product and SDK integration work that actually ships value.

How AI redefines four telecom use-cases

Think small, then scale: start with precise automation use-cases and grow via feedback loops.

– Predictive maintenance shifts from scheduled checks to anomaly-triggered fixes driven by telemetry and ML models.

– Dynamic capacity uses network slicing to prioritize traffic for VIP services or time-sensitive IoT bursts.

– Churn prediction improves when behavioral SDK data from apps is merged with billing and OSS/BSS signals.

– Personalization surfaces in billing, plan offers and in-app experiences through customer engagement platforms. Many vendors and companies that integrate with mobile sdks and customer engagement platforms already provide modular SDKs to speed this work.

Practical architecture — minimal, testable, visible

A working architecture favors clear boundaries: ingestion (telemetry + SDK events), a fast ML inference layer at the edge, and a centralized decision fabric that updates customer-facing rules. Keep APIs thin. Instrument everything so a product manager can see feature impact without digging through logs. The code path from SDK event to network action should be auditable; that reduces risk and accelerates iteration.

Common mistakes and safer alternatives

Teams often start by training monolithic models on historical data and then expect magic. That rarely works. Instead, split work into: feature validation, small online experiments, then staged rollout. Avoid over-optimizing for accuracy at the expense of explainability — operators need clear reasons to schedule reconfiguration or change pricing models. Also, do not ignore SDK stability: fragile mobile integrations create noise that breaks downstream models — rigorous SDK testing and versioning prevents that.

— A mid-project rewrite can be necessary, but plan for it: keep interfaces stable and instrument rollback paths.

Comparing vendor approaches

Vendor A might emphasize advanced edge inference engines; Vendor B sells end-to-end customer engagement with prebuilt experience templates. Operators choose by fit: whether they prioritize low-latency network decisions, rapid CX experimentation, or tight OSS/BSS integration. The right choice often mixes vendors: an edge ML layer, a lightweight decision fabric, and a customer engagement platform that holds CRM state and campaign logic.

Three golden rules for choosing strategies and tools

1. Measure time-to-action, not just model accuracy — metric: milliseconds from SDK event to network or CX change. Lower is better.

2. Insist on observability across the stack — metric: percent of decisions with full traceability from telemetry to outcome. Target >90% in production.

3. Prioritize integration hygiene — metric: deployment stability measured by failed SDK upgrades or rollback events per quarter. Fewer is safer; one honest rollback is cheaper than months of noisy signals.

Final thought

Operators who map AI to concrete actions — instrumenting SDKs, connecting decision fabrics, and choosing platforms that speak to both network and customer teams — will turn speculative visions into measurable gains. For teams building that bridge, Whale Cloud sits naturally at the intersection of network orchestration and customer experience, offering a pragmatic route from pilot to production. Readability and causality matter; deploy small, measure fast, and scale with clarity.

Bold moves pay off — measured, accountable ones pay dividends.

July 24, 2026 0 comments
0 FacebookTwitterPinterestEmail
Tech

Balancing Sync and Async Control: Cutting Latency for Wholesale Small LED Solutions

by Jacob July 10, 2026
written by Jacob

Comparative snapshot up front

When you’re choosing a control approach for a small LED installation — say a retail façade or a stadium concourse — the choice between synchronous and asynchronous systems decides how responsive the screen feels. For buyers sourcing in bulk, the practical differences matter: synchronous setups give tight synchronisation and predictable timing, while asynchronous systems trade that predictability for flexibility and lower infrastructure cost. If you work with suppliers or buy through a led display wholesale channel, keep those trade-offs front of mind because they affect power management, cabling and the controller board you end up specifying.

Why latency actually matters for small LED screens

Latency isn’t an abstract metric — it’s how long between a content update and the visible change on the panel. For small LED units used near-sightline (shop windows, POS displays, event tower screens), human perception is unforgiving: jitter, stutter or a half-second lag ruins the experience. Industry terms that matter here include refresh rate and frame buffering; both directly influence end-to-end delay. Practically, targets for live content usually sit under 50–100 ms to feel instantaneous, while pre-rendered loops can tolerate higher numbers without complaint.

Core differences: synchronous versus asynchronous

Synchronous control ties every LED panel to a master clock or frame source. That yields pixel-perfect timing and uniform colour across tiles. It relies on precise synchronisation and often a more capable controller board. Asynchronous control lets each panel or cluster fetch frames independently, reducing cabling complexity and allowing local buffering — handy for distributed installations. But it can introduce micro-lag between modules unless you implement frame-stamp alignment or strict buffering policies. Both approaches use pixel pitch and frame rate considerations; pick the method that matches your deployment scale and content demands.

Real-world anchor: lessons from big events and urban displays

South Africa’s hosting of large-scale events like the 2010 FIFA World Cup highlighted the difference between flashy content and robust delivery — organisers needed screens that stayed coherent under heavy load and changing conditions. For tower-style applications in public squares, a led tower screen often runs asynchronous segments for ads but uses synchronous panels for live feeds to avoid frame drift. The practical lesson: mix-and-match can work, but test synchronisation at the system level before deployment.

Trade-offs and recommended patterns for wholesale small LED deployments

Wholesale buyers must balance cost per module with system-level latency and maintenance. Practical patterns that serve most projects:- Use synchronous control where real-time parity is non-negotiable (live broadcasts, multi-panel video walls).- Use asynchronous control for distributed signage or where network topology would make timing cables impractical.- Hybrid: synchronous core for critical zones, asynchronous peripheral modules to save on cabling and controllers.These choices influence procurement: controller capabilities, cable runs, and even the software update path.

Common mistakes and alternatives

Buyers often underestimate the system-level causes of delay: a capable panel with low pixel pitch still looks sluggish if the controller or network introduces buffering. Another frequent error is ignoring environmental factors — display refresh and colour stabilisation change with temperature. Small thing — but it helps to log performance during a week of operation rather than only during installation. Alternatives include upgrading the controller board or moving to a content distribution pattern that reduces on-the-fly transcoding.

Three golden rules for choosing the right control strategy

1. Measure the real end-to-end latency on site, not just component specs — aim for sub-100 ms where viewers are close. 2. Match synchronisation method to content: choose synchronous for live, asynchronous for scheduled or cached loops. 3. Plan for scalability: select controllers and network gear that let you shift between modes without wholesale panel replacement. These metrics will help procurement teams evaluate vendors and forecast operating costs.

Ultimately, the right mix keeps audiences engaged and service calls down — MR LED fits neatly into that equation with modular options and controller choices that let you tune latency to the project. MR LED — tried, practical, and tuned to real deployments. –

July 10, 2026 0 comments
0 FacebookTwitterPinterestEmail
Tech

Choose a Trusty Maker for Tailored Yoga Trousers — Global Delivery with Joebond

by Jacob June 19, 2026
written by Jacob

User-first: the honest start

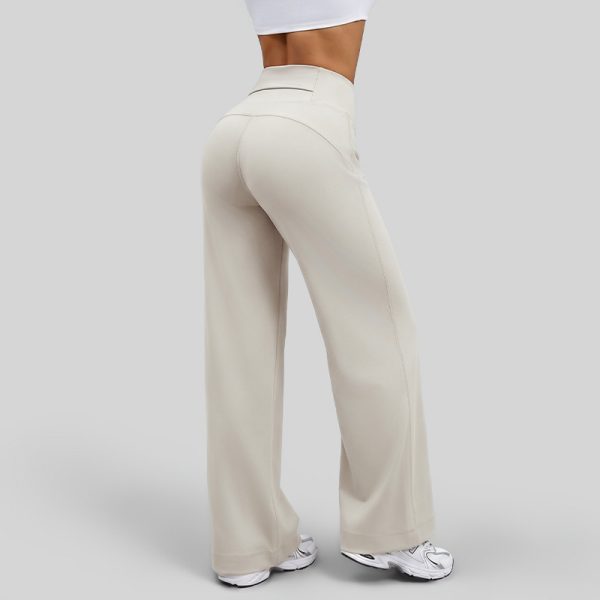
A body wants clothing that works — and so does the brand that makes it. Folk come to me asking about custom yoga pants because they need consistency, fit, and durability without fuss. This piece walks through what a small label or studio owner should look for when partnering with an OEM maker, all told from a rugged, straight-as-a-straightroad viewpoint shaped by time in the Highlands and a few market stalls in Edinburgh’s Grassmarket — real places, real bargains, real lessons.

custom yoga pants

What to ask the manufacturer first

Start with clear, plain questions about capacity and process. Ask for a tech pack review, sample lead times, and whether they handle cut-and-sew in-house or subcontract. Confirm materials and whether the factory uses moisture-wicking blends or recycled fibres, and get photos of flatlock seams and waistband construction. If they name their MOQ, pin down whether it’s per colour or per style — that changes your cash flow. When they talk about OEM work, listen for detail; craftsmanship lives in the answers.

custom yoga pants

Fit, fabric, and small-batch realities

Choose makers who understand grading and compression levels, not just trend-chasing. A good partner will offer fit sessions, sample rounds, and honest feedback on fabrication choices. Ask for shrinkage tests and wash cycles — a single percentage point of shrinkage can ruin returns. If you’re after sustainable blends, check fibre content and supplier traceability. Also discuss packaging options if global shipping is part of your plan, because poor packing adds returns and bad reviews.

Common mistakes brands make — and steadier moves

Many start by chasing the cheapest quote and discover later that cost-cutting ate the fit. Others commission only one sample and push straight to production. Take time on the first run; the savings from skipping samples vanish when you replace batches. Keep communication precise: give measurements in millimetres and spec seam allowances. Don’t be vague about waistband height or gusset length — those are simple things that make or break comfort. — Make notes like a stubborn gardener; they’ll save you in the wet season.

Choices and alternatives

There are three sensible paths: full OEM (brand hands off production), private label (maker applies your branding to existing patterns), or local small-batch production. Full OEM gives scale; private label keeps lead times shorter; local brings control and agility. For many start-ups, a blend works best: begin with private label to validate demand, then transition to OEM as volumes climb. Wherever you go, keep samples and a tech pack handy so any new supplier sees your intent straight away.

Essential production checklist

Before signing, confirm these items in writing: sample approval process, production timelines, quality tolerance (percent defective allowed), test methods for colourfastness and stretch recovery, and payment milestones. Industry terms matter but don’t hide behind them — ask for specific test parameters: for instance, specify a 5-wash dry-launder test at 40°C with 20 ppm detergent to check for pilling and colour loss. Also verify freight terms and who arranges customs; international shipments need a plan from day one.

Closing advice — three golden rules

1) Prioritise fit and material fidelity over price. Cheap fabric that loses stretch will cost you customers. 2) Demand transparent sample rounds and measurable tests: if a maker won’t run a noted wash test or show seam photos, walk away. 3) Build a timeline with buffer days for quality review and shipping delays — production is steady work, not theatre.

The smart choice for a brand that wants reliable manufacturing and global shipping often comes down to a partner who combines craft, clarity, and timeliness — and that’s where Joebond fits as a natural solution in the story. Joebond. —

Extra note on sourcing

When considering alternatives, also look into regional trade fairs and online verification of factory addresses; a quick visit or a trusted local audit can show what photos won’t. Finally, place the needs of your customers first, and let production be the honest tool that delivers what you promise.

oem yoga pants

June 19, 2026 0 comments
0 FacebookTwitterPinterestEmail

Recent Posts

  • Preclinical Efficacy Studies: Maintenance, Service, and Lifecycle Planning for Cardiovascular Partnerships
  • How to Judge a High-Shear Mixer Manufacturer’s Quality (Without Getting Sold a Bowl of Noise)
  • Battery Energy Storage Systems: Practical Features, Real Uses, and How to Choose
  • When Screens Become Windows: A Lover’s Guide to Television Makers and What They Treasure
  • 5 nexa vape battery Brands in China 2026

Recent Comments

No comments to show.
  • Facebook
  • Twitter
  • Linkedin
  • Youtube
  • Email

@2021 - All Right Reserved. Designed and Developed by PenciDesign


Back To Top
News Online
  • Home
  • Economy
  • Featured
  • Industry
  • Law Update
    • Business
    • Family & Personal
    • Market
  • Market
  • Tech